
Classification & splitting
Identify document type, separate mixed files and route each document to the correct schema and workflow.
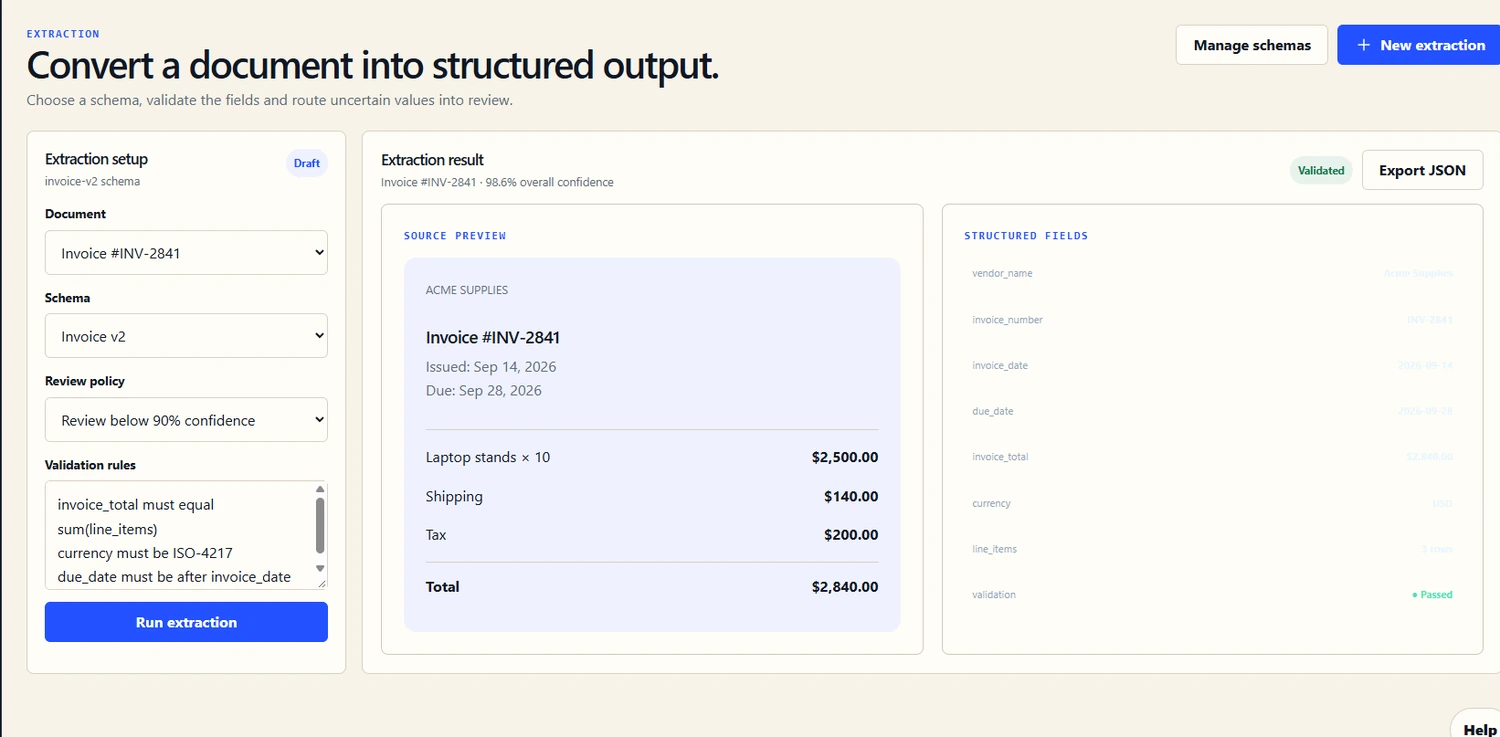
Classify, parse, extract, normalize and validate fields across complex layouts without building a separate workflow for every template.
Identify document type, separate mixed files and route each document to the correct schema and workflow.
Extract typed values, tables, line items, dates, entities and page references into structured output.
Combine model confidence with deterministic business rules and human review thresholds.
Define the fields your business process actually needs, then route document understanding into the same normalized structure regardless of source layout.
Preserve rows and headers across page breaks.
Process documents with varying templates and visual structures.
Route uncertain content into review instead of silently accepting errors.
Validate totals, required fields, dates and reference data after extraction.